Too Many Alerts, Not Enough Context
One issue triggers several alerts. Without correlation, teams chase symptoms separately, duplicate work and lose time finding the real cause.
Autonomous Ops helps engineering teams move beyond reactive operations by connecting incident detection, investigation, policy-driven decision-making, automated remediation and recovery verification into a coordinated workflow.
Verified recovery
toPrompt is a solution from The NineHertz, an AI-native engineering partner
Autonomous Ops is an approach to modern operations that combines incident intelligence, operational automation and policy-driven execution to help engineering teams respond to infrastructure and application issues more consistently.
Instead of treating every alert as an isolated event that needs manual investigation, Autonomous Ops connects signals to a structured incident lifecycle. It helps determine what is happening, evaluate the appropriate response, initiate permitted remediation and verify whether the underlying issue has been resolved. Incidents that need more oversight go to a person for approval, or are escalated to the right team.
The objective is not to remove engineers from the operational loop. It is to reduce repetitive intervention, make operational responses more consistent, and let engineers focus on the complex problems that need their expertise.
From detecting incidents to verifying recovery, bring more intelligence and control to every operational response.
One issue triggers several alerts. Without correlation, teams chase symptoms separately, duplicate work and lose time finding the real cause.
Restarts, deployment checks and routine recovery steps eat engineering time, even when the right response is already known.
Without clear policies, risk controls and approvals, automation forces a trade-off between speed and the impact of a wrong action.
Running a fix doesn’t mean it worked. Without post-action health checks, failures persist unnoticed instead of being escalated.
The next step in operational maturity is not simply generating more alerts. It is building a controlled path from incident signals to verified outcomes.
Six capabilities that take an incident from first signal to verified recovery, with control at every step.
Bring incident handling into a structured, traceable workflow. Every incident moves through the same defined stages: correlation, investigation, policy evaluation, execution, verification, and resolution or escalation. Each one is recorded with its history and checked against known incidents, so responses are consistent and fully traceable.
Identify related signals and cut unnecessary duplication. Duplicate and related alerts are grouped into a single incident, and secondary symptoms are suppressed once the root cause is identified. Cooldown controls stop the same fix from running repeatedly, so teams investigate one problem, not ten alerts.
Automate appropriate responses without giving up control. Policy rules, risk tiers and confidence thresholds decide whether an action runs automatically, needs approval or is escalated. Sensitive operations, such as payment-critical services, are restricted from automatic execution, and designated high-risk actions always require sign-off.
Connect operational decisions to defined remediation workflows. Permitted actions run through your controlled deployment workflows rather than direct infrastructure access, with defined permissions for what each workflow can do. Every change is authorised and traceable, and restart and rollback paths are available today.
Know whether an action worked, not just whether it ran. After every action, health checks confirm whether the service has actually recovered, with retries where needed. An incident is resolved only when recovery is verified; otherwise it stays open and moves to failure handling or escalation.
Keep engineers informed and in control of incidents, actions and decisions. Engineers receive incident notifications in Slack and can approve or decline proposed actions in one click. An operations console shows incident status and supports operational commands, so people can step in or escalate whenever a situation requires it.
A four-stage operational loop, with a decision point that keeps people in control of every action that needs them.
Operational alerts enter the incident workflow, where related signals are correlated to identify a shared underlying issue and build a coherent view before any response.
The incident is investigated and its context evaluated against defined policies. Incident type, confidence, risk classification and permitted actions determine the response.
If the action meets policy requirements, an authorised remediation runs. If it needs approval, or falls outside the rules, it is routed to a person or escalated.
After execution, the system checks whether the service has recovered. Verified recovery resolves the incident; otherwise it is preserved and sent for further investigation.
The decision point
Automate appropriate, repeatable responses to common incidents, so engineers spend less time on routine procedures and more on improving reliability and engineering performance.
Use defined workflows and policies to make operational responses more predictable, traceable and repeatable across supported incident types.
Apply risk-based policies, approval requirements and restricted execution paths to balance operational speed with the right level of oversight.
Make verification part of the incident lifecycle, so every action is judged by its outcome, not counted as successful simply because it ran.
Start with well-understood incident classes and controlled remediation, then expand automation as policies, integrations and operational evidence mature.
We establish your baseline first, then track mean time to acknowledge, mean time to recover, manual interventions per incident, repeat-incident frequency and verified remediation success.
The goal is not to automate everything. It is to automate the right things, within the right boundaries, and verify the results.
A service begins generating repeated errors. Instead of an engineer working through every step by hand, the workflow correlates related alerts, evaluates the incident against your policies and decides whether the fix can run automatically or needs approval. Once an action runs, a health check confirms recovery, or the incident is kept open and escalated.

What you’ll see
Accelerators built by the same AI-native engineering team.
From an idea to a production-ready application.
Turn application concepts into working software with AI-assisted development, and engineering support to take the product towards production.
Coordinate AI-driven workflows.
Orchestrate AI agents, tools and workflows across defined business processes.
Reduce the friction in sales operations.
Streamline CRM workflows, improve visibility and reduce repetitive sales administration.
Make support workflows more efficient.
Apply AI to ticket handling and support operations.
Your engineering teams should not have to repeat the same investigation and remediation steps for every incident. NineHertz helps you identify the right opportunities for operational automation, define the controls needed to run it safely, and build a path towards more consistent, intelligent operations.
Practical answers for engineering and operations leaders evaluating operational automation.
Autonomous Ops is an approach to operational automation that connects incident detection, investigation, policy-driven decision-making, remediation and recovery verification. It helps engineering teams automate appropriate operational responses while preserving oversight for actions that require approval or escalation.
Traditional monitoring tools primarily help teams collect signals, detect anomalies and raise alerts. Autonomous Ops extends the operational workflow by connecting incident context to policy evaluation, authorised remediation and post-action verification. The extent of automation depends on the integrations, supported incident classes and policies configured for your environment.
It is designed to support automated remediation for eligible incident types when the applicable policies permit it. Actions that require approval, or fall outside the automation rules, are routed for human intervention. The level of automated resolution depends on the supported workflows and your operational environment.
Risk tiers, policy rules, execution restrictions, approval workflows and verification gates work together to prevent inappropriate actions and make sure certain operations always receive additional oversight. The controls for each deployment are defined and configured with your team.
Eight incident classes are defined, covering scenarios such as service error rates, data-relay failures, database availability, pod failures, latency and message-queue consumer lag. The level of automation differs by class: some can be remediated automatically, some require approval and some always escalate to a person.
Some incidents may qualify for policy-approved automation, while others require explicit approval or escalation. The intended approach is to automate appropriate tasks without removing human judgement from operational decisions.
The reference architecture works with monitoring and alerting tools, Slack, GitHub Actions, ArgoCD and Jira. The integrations available for your environment are confirmed during scoping, before they are relied on in production.
Start by assessing your existing incident management process, identifying repetitive operational tasks and determining which remediation actions can be automated safely. NineHertz can help define the initial use cases, establish the necessary policies and controls, and develop an implementation roadmap aligned with your operational environment.
Perspectives on AI, engineering, and the future of software development
Key Takeaways Staff augmentation buys capacity that you direct. Project outsourcing buys…
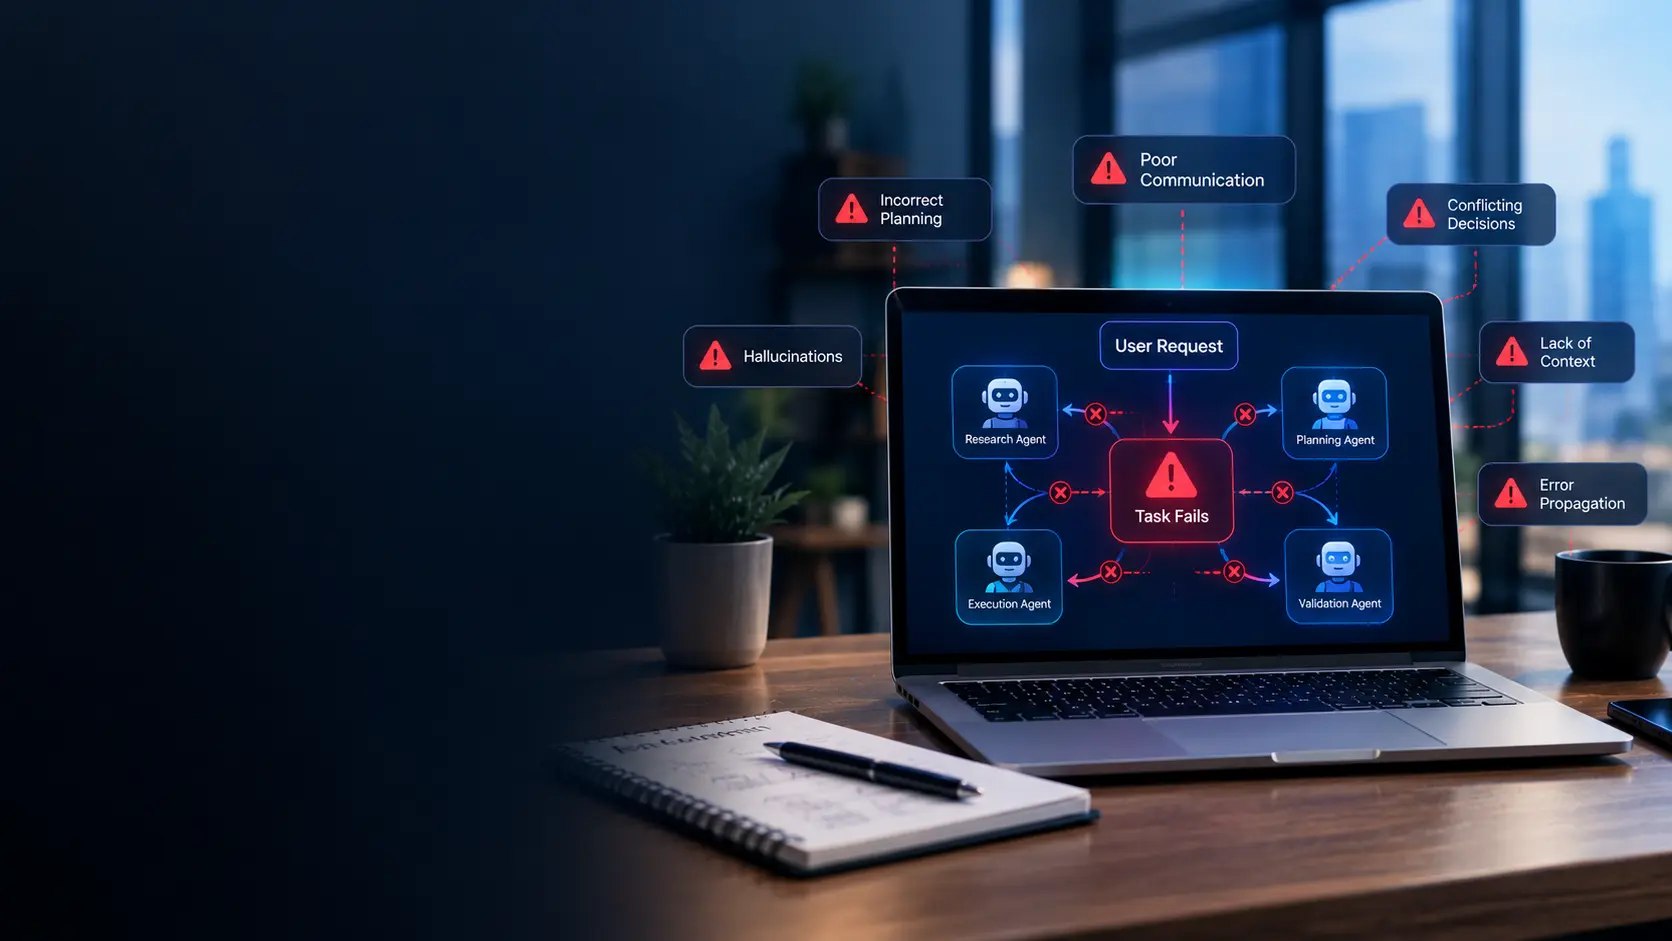
Key Takeaways According to statistics, multi-agent systems have a 41% to 86.7%…
Have you ever created a super-smart AI agent that no one actually…
Technology surrounds our lives like for real! We can use Gmail, WhatsApp,…
Key Takeaways IP architecture is not a legal formality bolted onto an…

Key Takeaways Offshore software development is a hiring model which enable the…