The demo went well. The agent read the support ticket, looked up the customer, checked the order history, drafted a refund and explained its reasoning. The steering committee approved a pilot. Six months later the agent is still in the pilot: it handles a few hundred cases a week under close supervision, nobody can say what it saves, the cloud bill is higher than expected and the security team has questions nobody can answer.
This pattern has a name, pilot purgatory, and agentic AI is especially prone to it. An agent doesn’t just generate text; it takes actions in systems of record. That’s where the value is, and it’s also why the path from pilot to production is harder than for any AI project that came before.
This guide explains why enterprise agentic AI projects fail, what changes between a pilot and production, and the practical steps that let technology leaders scale beyond the pilot with confidence.
Enterprise agentic AI projects fail when organizations treat agents as a model experiment instead of a production system. The model is rarely the problem. Projects stall on unclear business ownership, unreliable data and integrations, missing evaluations and monitoring, unmanaged cost and autonomy that nobody has defined or governed.
At The NineHertz, where we build agentic AI development solutions for enterprises, we see the same turning point in almost every engagement: the moment a working proof of concept meets decade-old infrastructure. Scaling beyond the pilot means engineering for that moment. In practice that means redesigning the workflow around the agent, connecting it safely to the systems it must use, testing it continuously, setting autonomy by risk under a governance framework such as ContinuumAI™, and proving business value before expanding.

The failure rate of AI projects is not new. A 2024 RAND study, based on interviews with 65 experienced data scientists and engineers, notes that by some estimates more than 80% of AI projects fail, twice the rate of IT projects that don’t involve AI. RAND traced the causes to leadership misalignment, inadequate data, technology chosen for its novelty rather than the problem, underinvestment in infrastructure and problems beyond the state of the art.
Agentic AI adds new reasons to that list:

A predictive model returns a score, and a person decides what to do with it. A generative AI assistant drafts text that a person reviews. An agent plans a sequence of steps, calls tools, reads and writes data and takes actions, sometimes without a person in the loop. Three properties make that harder to scale than other forms of AI development.
Errors compound across steps. Each step an agent takes, such as interpreting the request, choosing a tool, retrieving data or writing a record, has a chance of going wrong. Small error rates multiply. If an agent gets each step right 95% of the time, it completes a 10-step task correctly only about 60% of the time (0.95 to the power of 10). At 90% per step, end-to-end success falls to about 35%. Pilots hide this because they use short, clean tasks and close supervision.
Behavior is non-deterministic. The same input can produce different plans. Traditional test suites, which assume the same input always gives the same output, can’t certify an agent on their own. Teams need evaluation sets, graded outcomes and regression testing for every change to prompts, models or tools.
Agents act with real permissions. An agent that can issue refunds, change records or send messages carries the access rights of a system user. Permissions that were acceptable in a sandbox become a security, compliance and audit question in production.
Anthropic’s engineering guidance on building agents reflects the same lesson. It reports that the most successful implementations weren’t using complex frameworks or specialized libraries, recommends “finding the simplest solution possible, and only increasing complexity when needed”, and notes that agentic systems “often trade latency and cost for better task performance”. For many enterprise processes, a well-designed workflow with one or two model calls beats a fully autonomous agent. Choosing the right level of autonomy is the first scaling decision, not the last. For multi-agent designs in particular, see our analysis of why multi-agent LLM systems break down.

When enterprise agentic AI projects fail, the causes fall into four groups. Most stalled projects show at least one from each.
| Failure mode | How it shows up in the pilot | What it costs at scale | The fix |
|---|---|---|---|
| No business owner | Steering committee enthusiasm, no KPI owner | No path to production budget | Name a process owner with a value target before the pilot |
| Agent where a workflow would do | Impressive demo, long reasoning chains | High cost, low reliability | Start with the simplest design; add autonomy only where it pays |
| No baseline | “It feels faster” | Project cut at budget review | Measure cost, cycle time and error rate before go-live |
| Demo-grade data | Works on curated cases | Wrong actions on real records | Data quality checks and retrieval grounded in owned sources |
| Brittle integrations | Scripts and manual steps | Outages under volume | Stable APIs, idempotent actions, retries and fallbacks |
| Broad permissions | Shared service account | Security review stops rollout | Agent identity, least privilege and scoped tools |
| No evaluations | Manual spot checks | Every change is a risk | Evaluation set of real cases, run on every change |
| No observability | Logs nobody reads | Incidents can’t be explained | End-to-end traces, dashboards and alerts |
| Unmanaged cost | Small volumes hide it | Cost per task exceeds value | Cost budgets per task, model routing and caching |
| Undefined autonomy | Human checks everything | Either blocked or unsafe | Risk-tiered autonomy with approval points |
| Workflow not redesigned | Agent mimics old steps | Little measurable gain | Redesign the process around agent and human roles |
| No change plan | Pilot users are volunteers | Low adoption | Train reviewers, define exception handling, share results |

Most pilots answer one question: can an agent do this task? Production asks a different one: can the business rely on it every day, at scale, safely and at a known cost?
| Dimension | In the pilot | In production |
|---|---|---|
| Data | Curated sample cases | Full, messy, changing records |
| Users | A few volunteers | Hundreds of employees or customers |
| Permissions | Broad test access | Agent identity, least privilege, audit trail |
| Integration | Scripts, sandboxes and manual steps | Stable APIs, error handling and fallbacks |
| Quality assurance | Spot checks | Evaluation suite, regression tests and sampling |
| Monitoring | Occasional log review | Traces, dashboards, alerts and incident response |
| Cost | Ignored at low volume | Budget per task, tracked monthly |
| Autonomy | Human reviews everything | Defined by risk, with approval points |
| Ownership | Innovation or data team | Business process owner plus a team that runs it |
| Success measure | “The demo worked” | Business KPI moved, at an acceptable cost and risk |

Before approving the move from pilot to production, leadership teams can score the initiative on eight dimensions, from 0 (not started) to 3 (production-ready). The scorecard is a NineHertz working tool, not an industry standard, but it gives executives a shared language for the decision.
| Dimension | What “3: production-ready” looks like |
|---|---|
| Business ownership and value | A named process owner, a baseline and a target for the business KPI |
| Workflow design | The process has been redesigned around agent and human roles, with exceptions defined |
| Data readiness | Sources are owned, current and permission-aware; quality is checked |
| Integration | Stable APIs, safe retries, fallbacks and tested failure modes |
| Evaluation | An evaluation set of real cases, pass thresholds and regression testing on every change |
| Observability and operations | End-to-end traces, alerts, an on-call owner and an incident process |
| Security and governance | Agent identity, least privilege, risk-tiered autonomy, audit trail and policy sign-off |
| Cost control | Cost per task measured, budgets set and optimization in place |
How to read the total (out of 24): below 12, keep it in the lab and fix the foundations; 12 to 18, run in limited production with close supervision; above 18 with no dimension below 2, scale.
Find the gaps holding your agentic AI pilot back from scale.

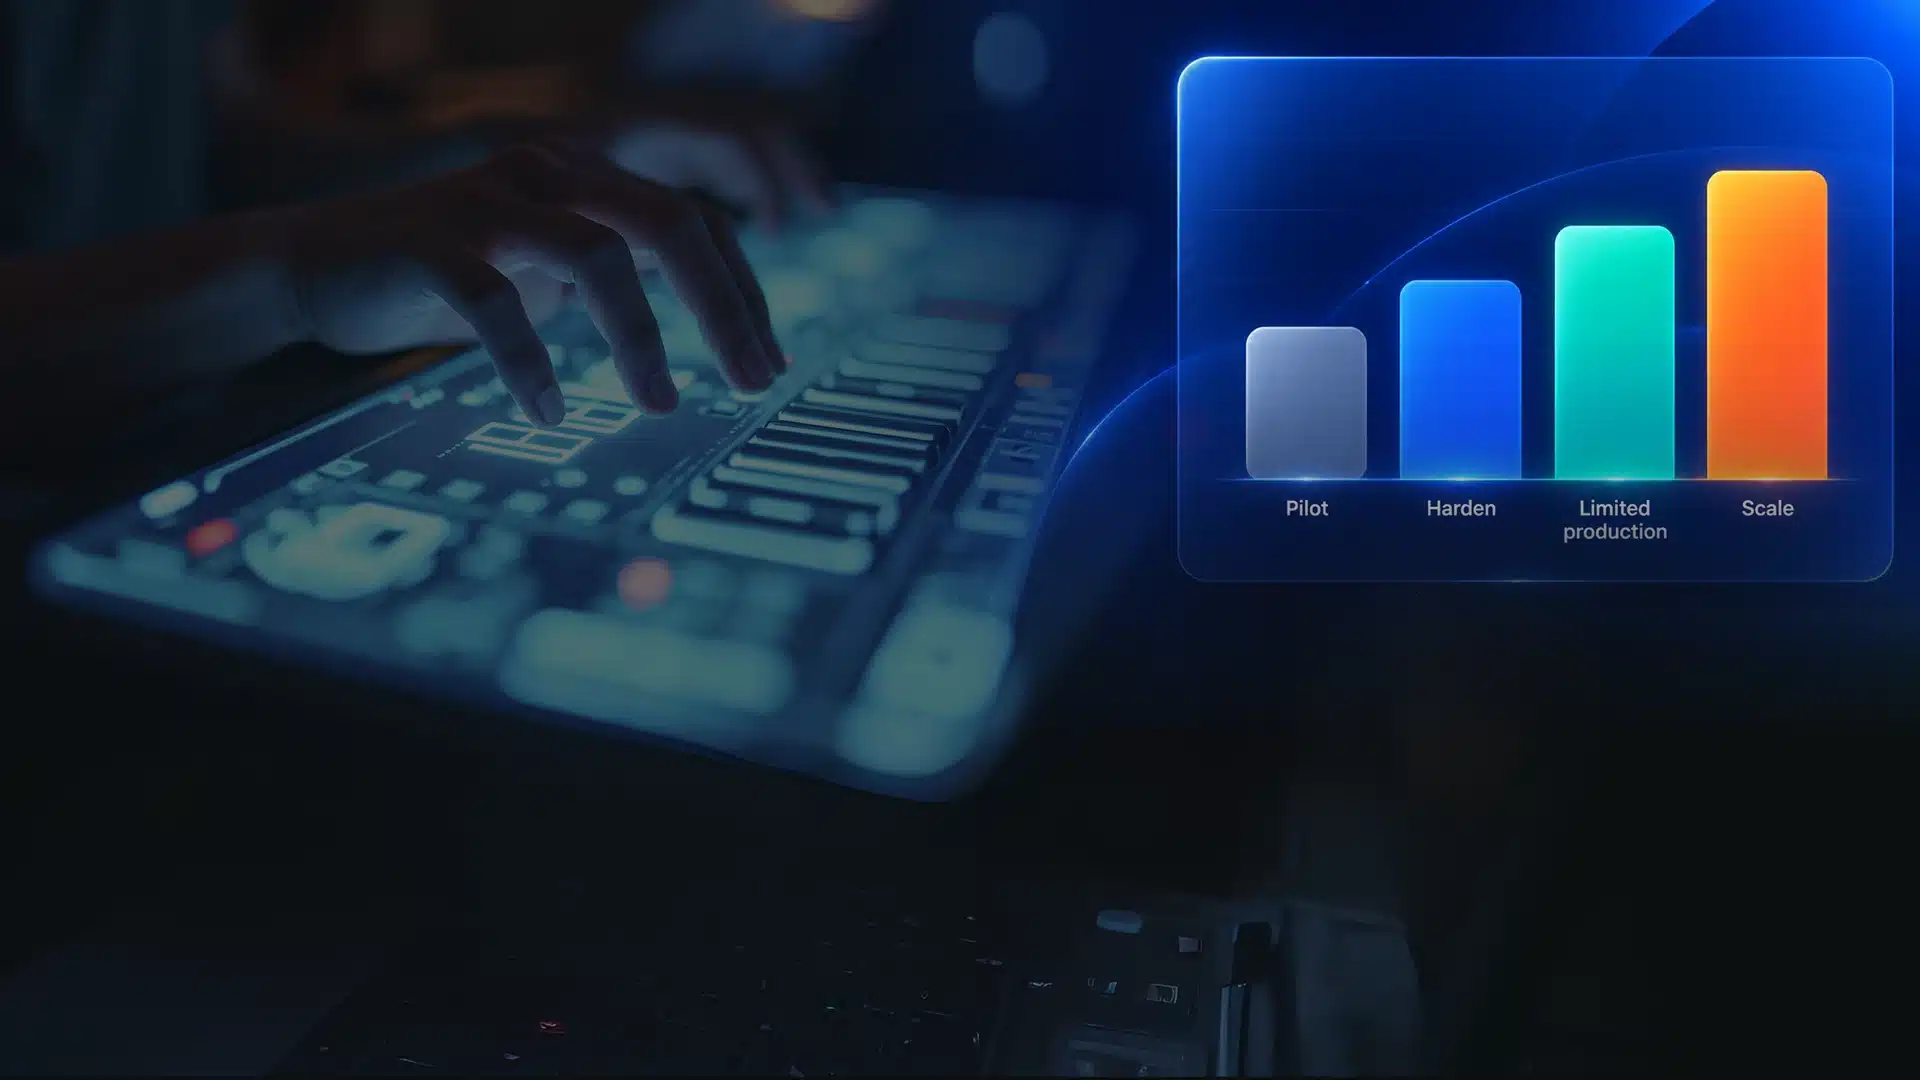
Scaling beyond the pilot is not a single launch. It is a sequence of gates, each with evidence the steering committee can review.
Days 0–14: Diagnose. Confirm the business owner, baseline and value target. Map the workflow, data sources, integrations and risks. Score the pilot on the readiness scorecard and decide what must change. NineHertz’s AI Delivery Readiness Diagnostic is a fixed-fee, two-week engagement designed for exactly this step.
Days 15–45: Harden. Build the evaluation set and pass thresholds. Replace scripts with stable integrations; we cover the patterns in connecting agents to the systems you already run. Give the agent its own identity and least-privilege access. Add tracing, cost tracking and alerts. Simplify the design wherever a workflow beats an autonomous step.
Days 46–75: Run in limited production. Start in shadow mode, where the agent proposes and people decide. Move to human-approved actions, then to bounded autonomy for low-risk actions. Track the business KPI, override rate, incident rate and cost per task every week.
Days 76–90: Make the scale decision. Review the evidence against the value target and risk thresholds. Scale, adjust or stop. Stopping a project with clear evidence at day 90 is a success compared with keeping it in pilot purgatory for a year.
Many agentic AI projects fail at the budget review rather than in production: they are canceled not because they didn’t work but because nobody could prove they did. Agree the measures before the pilot starts.
Monthly net value = (tasks handled × (baseline cost per task − agent cost per task)) + value of faster cycle time and fewer errors − platform, oversight and maintenance costs
Agent cost per task must include model usage, tool and API calls, infrastructure, and the human time spent reviewing and handling exceptions. Our guide to forecasting and controlling AI agent costs covers the cost side in detail.
| Metric | What it tells you | Typical owner |
|---|---|---|
| Business KPI (for example cost per case, cycle time, revenue recovered) | Whether the agent creates value | Process owner |
| Cost per task | Whether value exceeds cost at volume | Finance and engineering |
| Task success rate on the evaluation set | Whether quality is stable across changes | Engineering |
| Human override rate | Whether people trust the agent’s output | Process owner |
| Autonomy rate | How much work runs without approval, by risk tier | Risk and process owner |
| Incident rate and time to resolve | Whether failures are contained | Operations |
Insight: The most useful early indicator is the human override rate. If reviewers keep correcting the agent, there is a quality, data or workflow problem that more autonomy will only amplify. If overrides fall steadily while the business KPI improves, you have the evidence to expand.
Governance is often blamed for stalled agentic AI projects. More often, the problem is that governance arrives late and applies one rule to every agent. Gartner has warned that applying uniform governance across AI agents will lead to enterprise AI agent failure, and recommends steps to manage agent sprawl, including:
The practical principle is autonomy proportional to risk. An agent that summarizes documents needs light controls. An agent that changes customer records needs approval points and audit trails. An agent that moves money needs strict limits, human sign-off above thresholds and continuous monitoring. At NineHertz, ContinuumAI™ is the framework we use to set these controls across the delivery lifecycle, and our approach to AI governance and risk explains how it fits with existing security and compliance processes.
Scaling also depends on who builds and runs the agent.
Whichever route you choose, the same production disciplines apply: evaluation, observability, cost control, governance and a business owner.
If the team can’t answer these, the project isn’t ready to scale, and that is a far cheaper discovery before the rollout than after it.
Agentic AI projects don’t fail because enterprises chose the wrong model. They fail because a pilot was asked to become a product without the engineering, ownership and governance a product needs. The organizations pulling ahead redesign the workflow, connect agents safely to their real systems, test and monitor them continuously, set autonomy by risk and prove value before expanding. Scaling beyond the pilot is less about smarter agents and more about the disciplined engineering around them.
Get a clear plan to move your pilot into production.
Most fail for organizational and engineering reasons rather than model quality: no business owner or baseline, data and integrations that only worked in the demo, no evaluations or monitoring, cost per task that exceeds the value created, and autonomy that was never defined or governed. Gartner predicts more than 40% of agentic AI projects will be canceled by the end of 2027 because of escalating costs and unclear business value.
Pilot purgatory is when an AI project works well enough in a pilot to avoid cancellation but never earns the evidence, ownership or engineering needed to reach production. It keeps consuming budget and attention without delivering business value at scale.
McKinsey’s State of AI in 2026 survey found that about two in ten organizations are scaling AI agents across the enterprise. Among organizations with more than $1 billion in revenue, 40% report scaling agents, up from 27% a year earlier.
Agents take multi-step actions in real systems, so small error rates compound: an agent that is right 95% of the time per step completes a 10-step task correctly only about 60% of the time. Agents are also non-deterministic and act with real permissions, which raises testing, security and audit requirements.
A structured path typically runs in four gates over about 90 days: diagnose (around two weeks), harden the evaluation, integration, security and monitoring (about a month), run in limited production with increasing autonomy (about a month), then make an evidence-based scale decision. Complex integrations or regulated processes can take longer.
Compare the cost, cycle time and error rate of the process before and after the agent, and include the full agent cost per task: model usage, tools, infrastructure and the human time spent reviewing and handling exceptions. Track the business KPI, cost per task, task success rate, human override rate, autonomy rate and incident rate.
Set autonomy in proportion to risk rather than applying one rule to every agent. Keep a central inventory of agents, give each agent its own identity and least-privilege permissions, control what data it can access, keep an audit trail and monitor for agents acting outside their scope.
When it comes to PWAs, the sky's the limit in terms of scope and potential. Whether you're looking to create…
The world of NFTs is still very new, and it's hard to predict where the trend will go next. However,…
The global car wash services market witnessed unprecedented growth with the continuously increasing popularity of mobile apps like Spiffy, Washos,…