The increasing scale of AI usage across industries is eroding control over data sovereignty and compliance. According to Fortune Business Insights, the global AI governance market is valued at $351.7 million in 2026, further growing at a CAGR of 25.30%, expected to achieve a valuation of $2,140.8 million by the end of 2034. The gap between AI deployment and its proper control system widens with every release, mainly due to ambiguous pipelines, fragmented ownership, and unsanctioned tools.
AI data governance talks about the collection, categorization, access monitoring, accountability policies, controls, and the overall structure that governs data throughout the AI lifecycle. It also includes the complete analysis and categorization of data used for training, the prompts, the pipelines for data retrieval, and the outputs from the models.
Businesses are heavily using AI for their operational workflow without waiting for approved tools and authorised data sourcing. In the past few years, the gap between artificial intelligence applications and their ethical control has grown. For instance, Kiteworks research found that 65% of organizations reported shadow AI in their workflows, as employees routed sensitive data through unapproved tools. The EU AI Act and expanding US state AI laws are turning this uncertainty into regulatory liability.
This article covers important aspects of an AI data governance framework, challenges businesses face, a 6-step implementation pathway, sample best practices, and key indicators of success.
AI data governance is the control of data that goes into, through, and out of AI systems. This includes training and tuning the datasets, prompts, retrieval sources, and model outputs. It provides ownership, access, and privacy controls, logs lineage, and conducts bias and drift telemetry runs, meaning that all AI decisions can be traced back to approved and auditable data.
Governance follows the loop of data sourcing where the AI models keep learning and generating new data that flows into decisions, customer messages, and the next training cycle.
Pro tip: Engineering, legal, and security teams must work collaboratively on a single written governance policy, so that they can unitedly look after the whole AI lifecycle.
Traditional governance protects data at rest and in reporting, while AI data governance protects it in motion, through training, retrieval, and generation. The following table compares the two across five dimensions.
| Dimension | Traditional Data Governance | AI Data Governance |
|---|---|---|
| Scope | Warehouses, databases, and reports. | Data plus models, prompts, embeddings, retrieval indexes, and outputs. |
| Data Types | Mostly structured, tabular records. | Structured data plus unstructured content: documents, email, chat logs, images, audio. |
| Lifecycle | Largely linear (collect, store, use, retire). | A continuous loop (ingest, train, deploy, retrieve, generate, retrain). |
| Risks | Poor quality, unauthorized access, inaccurate reporting. | Biased training data, prompt leakage, memorization, stale or poisoned retrieval content, unexplainable outputs. |
| Ownership | Data owners and stewards, usually inside IT or a data office. | Shared across data, ML, security, legal, and the business, often under an AI governance committee. |
The difference between the two terms is greatest in the aspect of the lifecycle. The delay in finding errors due to manual inspection leads to a loop of flawed data movement throughout the generation and model retraining.
Binding regulation, unsanctioned AI use, data leakage through generative tools, and AI systems with direct access to enterprise data are the four key driving forces of modern control convergence.
Under Articles 6 and 10 of the EU AI Act, the data aspects that affect the quality of AI outputs are now legislated. The California AI Act (AB 2013) will require developers of generative AI tools to make summaries of the training data they use available starting 1 January 2026. Colorado has scrapped the 2024 AI Act and instead introduced a more limited law in effect from 1 January 2027.
The NIST AI Risk Management Framework builds control around four functions that are govern, map, measure, and manage. It also added a Generative AI Profile in July 2024 that lists data privacy among its twelve risk categories. Texas offers an enforcement safe harbor to organizations that substantially follow the framework.
Shadow AI converts regulatory exposure into breach cost. IBM’s 2025 research tied 20% of breaches to shadow AI, adding up to $670,000 per incident and disproportionately exposing customer PII and intellectual property. Among organizations with AI-related breaches, 97% lacked proper AI access controls, and 63% of breached organizations had no AI governance policy.
Enterprise agentic AI needs the same ownership, classification, and audit trail you would demand of any privileged user.
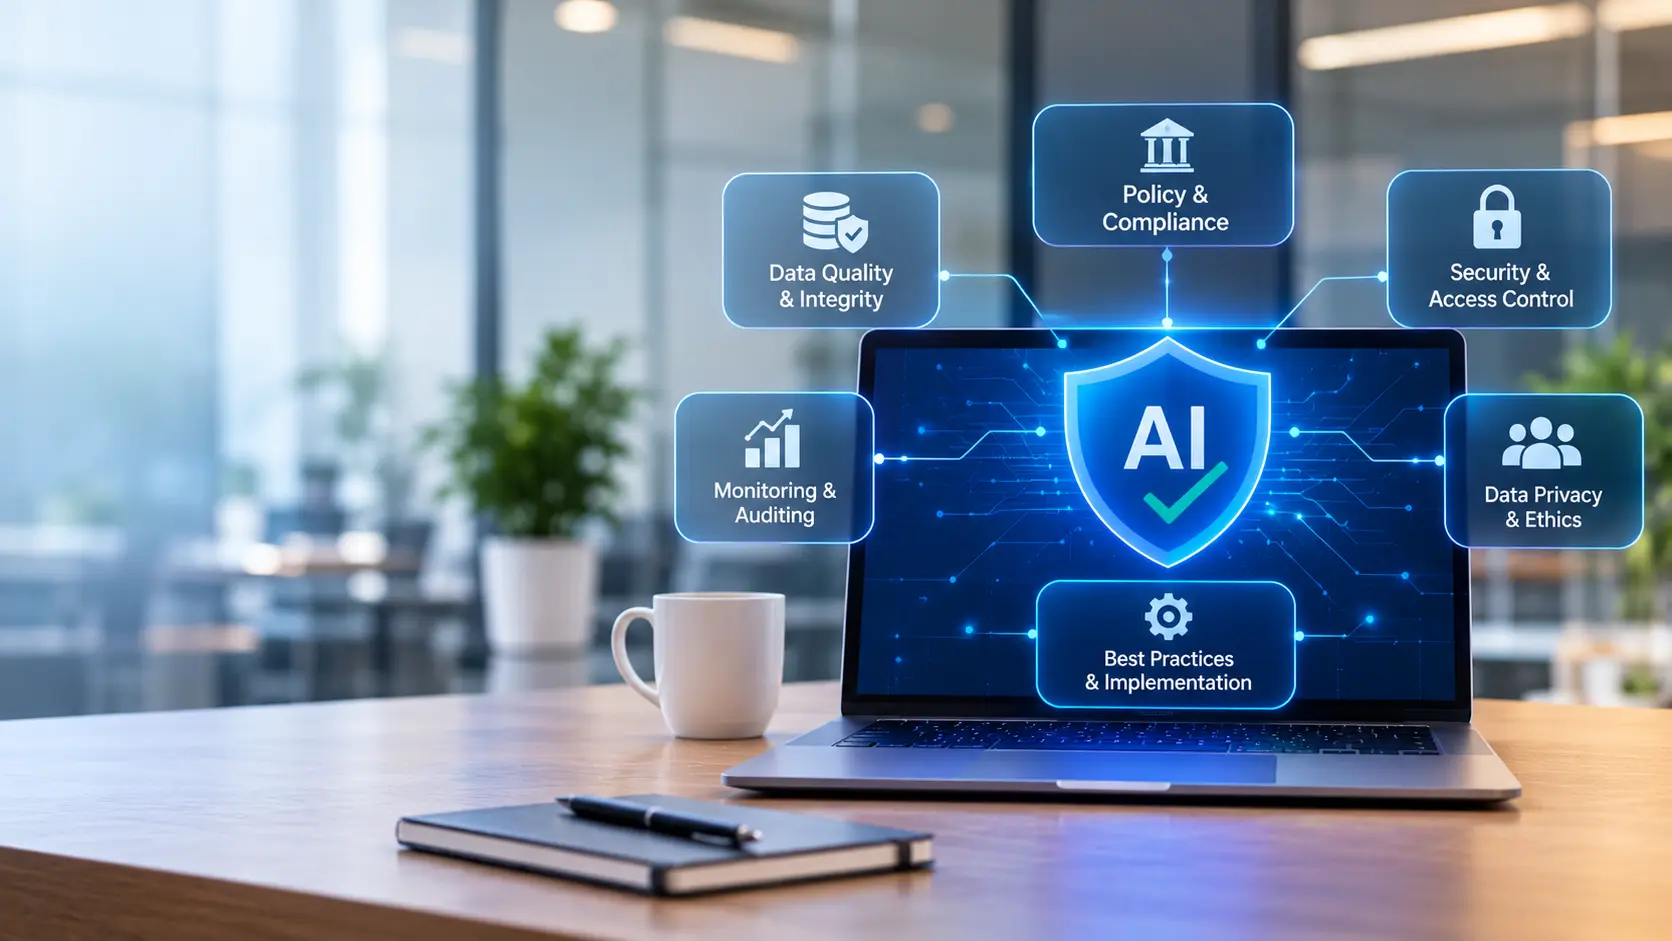
An AI data governance framework relies on six components, each closing a different gap between raw data and a model’s output:
Quality and lineage tell you whether you can trust a model’s input and provide proof of data sourcing. As per Gartner’s study, the average annual cost of poor data quality stands at $12.9 million, and a model repeats every flaw it learns. Set measurable thresholds for completeness, accuracy, and freshness at ingestion. Then capture lineage from source system through feature store, vector index, and output.
Pro tip: Block failing datasets at the pipeline gate instead of flagging them in a report.
These controls decide the source, type, user, and purpose of data. Apply role- and attribute-based access to training sets, retrieval indexes, and prompts. Mask or tokenize personal data before a model sees it. Extend identity controls to service accounts and agents, which now touch data the way employees do.
Documentation turns training data into an auditable record. For every model, log dataset sources, licensing and consent status, collection dates, preprocessing steps, known gaps, and version history.
Bias enters through data long before it shows up in a model. Test training sets for representation gaps, then run telemetry on output disparities across groups after launch. It safeguards the model from reintroducing bias that passed pre-release checks.
Build a matrix that represents controls as rows, and the EU AI Act, state laws, sector rules, and the NIST AI RMF as columns. Mapping links each control with the obligations of an owner and review data, enabling quick remapping.
Without clear ownership, frameworks fail. Kiteworks discovers that 39% of organisations view AI data governance as an additional function within an existing position, with only 24% having a dedicated team. ML leads document models, security owns access, and an AI governance committee settles risk-tier disputes and signs off on high-risk use cases.
Get visibility into every AI system, enforce controls inside your pipelines, and stay ahead of changing AI regulations.
Governance programs usually stall in five places, and spotting them early provides the framework from the previous section to learn from:
Gartner estimates unstructured data makes up 70% to 90% of enterprise data, and AI systems consume most of it. Information without dedicated labels is hard to track, govern, and secure at scale, creating major AI data governance bottlenecks. Partial visibility, uncertain classification, and an increase in sensitive data across enterprises are the dominant control, security, and governance concerns.
Employees tend to embrace AI faster than policies designed to manage its lifecycle, leading to the use of unapproved tools. Data leakage, compliance violations, IP exposure, and greater cybersecurity risks are the main consequences of shadow AI at work. A restriction on the use of AI across the organization’s workflow does not guarantee visibility and security, but an approved tool with logging permission does.
Embedding and vectoring processes are the core pain points in lineage gaps that consume 30% to 50% of RAG project cost. Large documents are broken into chunks, then converted into mathematical vectors, creating transformation blind spots with identical chunks and embeddings.
Data teams and ML teams both own tables and models separately, while the retrieval index works as a bridge between them. Most of the organization lacks well-defined accountability and coordination across the AI lifecycle and runs it at the department level. Each team assumes the other approved the dataset. Shared ownership has to be built into machine learning development workflows from the first sprint, not added after release.
MultiState’s tracker shows that 1,561 AI bills were introduced in the first quarter of 2026 alone in 45 states, and the Justice Department is targeting state AI laws for federal preemption, despite there being no preemption legislation. EU deadlines have also been pushed back until 2027 and 2028. A program that is built around the text of the statute is old-fashioned when it ships. A churn is absorbed by controls that are mapped to obligations.
AI data governance implementation runs in six steps, and each provides the inputs for the next in the hierarchy:
List every AI system in use, including models you built, vendor tools, copilots, embedded features, and agents. For each, record the data it reads and writes, the owner, and the vendor. Start with a SaaS and network discovery sweep, then survey business units for what the sweep misses.
The initial phase is labeling data according to its sensitivity level (public, internal, confidential, or regulated), after which particular use cases should be prioritized based on the possible negative impact of their implementation. The risk-based approach of the EU AI Act can serve as a reliable basis for regulation even for companies that only operate within the United States. For example, an AI-based chatbot that automatically composes responses using information retrieved from public resources would be assigned a low risk level, while a system that scores loan applications based on personal data would be placed at the highest level. The former would undergo fewer review stages before deployment with less frequent monitoring after launch.
Write policies at the level of decisions, not principles. Specify which data classes may enter which tools, who approves a new training dataset, how long data is retained, and what happens when a model is retired. Name an accountable owner for every AI system and every critical dataset.
Move enforcement into the pipeline itself. Add classification and quality gates at ingestion, masking before data reaches a model, permission checks at retrieval time, and lineage capture at each hop. A control inside the pipeline runs on every job. A control that lives in a review meeting runs on reminders. Treat these checks as code, versioned, tested, and deployed with the pipeline they protect.
Set up telemetry for data drift, output bias, access anomalies, and policy violations, and route alerts to named owners. Keep audit evidence continuous through logs, lineage records, and approval history. Send the governance committee a quarterly summary covering risk by tier, open exceptions, and incidents.
Schedule a formal review at least twice a year, and trigger an extra one after a new regulation, a major model change, an incident, or a new vendor. Retire controls that only generate noise, tighten the ones that missed an incident, and re-tier use cases as they change.
Five practices separate programs that survive an audit from the ones that live in slide decks:
Add a governance gate to AI project intake. Before the build begins, the team names its data sources, risk tier, and owner, and nothing enters production without sign-off. Fixing a consent gap in a live model decides whether it would be retrained or taken offline. It would have taken hours to fix at the design review.
Manual tagging cannot keep pace with unstructured data. Classify new content automatically on arrival, apply masking by sensitivity label, and write lineage records as a byproduct of every pipeline run. Reserve human review for low-confidence labels and exceptions.
Prompts and retrieved context are data that flows as inputs and outputs, so treat them with the same care as the rest of the critical data. Before a question leaves your systems, remove sensitive details such as customer IDs or health records. Make sure the AI presents the document to only authorised users, and do not keep chat logs for a long time.
A data contract is a written agreement between a dataset’s producer and its consumers. It states the schema, freshness, sensitivity labels, permitted uses, and who gets notified of breaking changes. Contracts close the ownership gap between data and ML teams by attaching a named owner and explicit terms to every dataset.
Use the tiers from Step 2 to decide where a person must review outputs. The EU AI Act requires human oversight for high-risk systems, and the logic holds for any decision touching credit, hiring, health, or legal status. Give reviewers the authority to override and the evidence behind each recommendation. A rubber-stamp review adds cost without adding control.
Classification, lineage, and access controls built into every AI system we engineer.
Measure three things: how much of your AI estate is governed, whether the controls work, and if the risk is reducing. Baseline each KPI during the Step 1 inventory, then report quarterly to the governance committee.
| KPI | What It Measures | Healthy Trend |
|---|---|---|
| Inventory Coverage | Share of AI systems registered with an owner and a risk tier | Toward 100% |
| Classification Coverage | Share of data feeding AI that carries a sensitivity label | Up |
| Lineage Coverage | Share of production models and RAG indexes with traceable source-to-output lineage | Up |
| Shadow AI Detections | Unapproved tools found per quarter | Rises first, then falls |
| Time to Remediate | Median days from a flagged violation to closure, including erasure across vector stores | Down |
| Incident Rate and Detection Time | AI data incidents per quarter and mean time to detect | Down |
| Audit Readiness | Hours needed to assemble evidence for a model audit | Down |
Pair each KPI with an owner and a target, because a number nobody owns drifts unchecked. Tier the results as well. A gap in a low-risk chatbot matters far less than the same gap in a loan-scoring model.
Pro tip: Brief leadership before the first report. Shadow AI detections will climb as discovery improves, and without context, that rise looks like failure.
AI data governance works when it starts with visibility and ends with evidence. Inventory what you run, tier it by risk, and place enforcement inside your pipelines instead of in policy documents. Assign named owners, report coverage every quarter, and review the framework whenever a regulation or a model changes. Start now, and you’ll have audit evidence before a regulator asks for it, rather than rebuilding controls under deadline pressure.
Governance succeeds when technology and policy move together, which is where an engineering partner earns its place. The NineHertz is an AI-native engineering firm that provides a comprehensive suite of services focused on the Build, Run, and Evolve framework. As the firm builds generative and agentic AI into its own development lifecycle, it works directly with the data flows that guide coverage, from training data to retrieval pipelines and agent access. Through its ContinuumAI framework, it helps ISVs, digital natives, and enterprises in healthcare, finance, and logistics govern the data behind legacy modernization and autonomous workflows, as a long-term technology partner rather than a one-time auditor.
AI governance covers the whole AI program, such as approving use cases, managing model risk, ethics, and accountability. Whereas AI data governance is the data layer inside it. It controls how the input and output data of AI systems are sourced, classified, accessed, and traced. Most programs need both.
While teams are responsible for collaboration, every piece of information must have an owner in charge of approving the use of the dataset, while stewards ensure quality and classification, ML leads document the models, and security restricts access to data. The AI governance committee can be formed to review disagreements about the risk level and approve the most at-risk use cases.
Start with an inventory of every AI system and the data it reads and writes, including owners and vendors. Then classify the data and tier each use case by risk. Those two steps give you a baseline. Policies, pipeline controls, and monitoring build on it.
The EU AI Act sets data governance duties for high-risk systems under Article 10, with deadlines moved to December 2027 and August 2028. In the US, state laws such as Texas’s TRAIGA already apply. The NIST AI RMF is voluntary but widely used as the common reference.
Track inventory, classification, and lineage coverage, time to remediate violations, incident rate with detection time, and shadow AI detections. Baseline each KPI during the inventory step and report quarterly. Expect shadow AI detections to rise at first, because better discovery finds more of what was already there.
Key Takeaways Bringing in an outside AI team makes sense when you want AI inside your product or workflows but…
Key Takeaways Most enterprise agentic AI projects don't fail because the model is weak. They fail where a working demo…
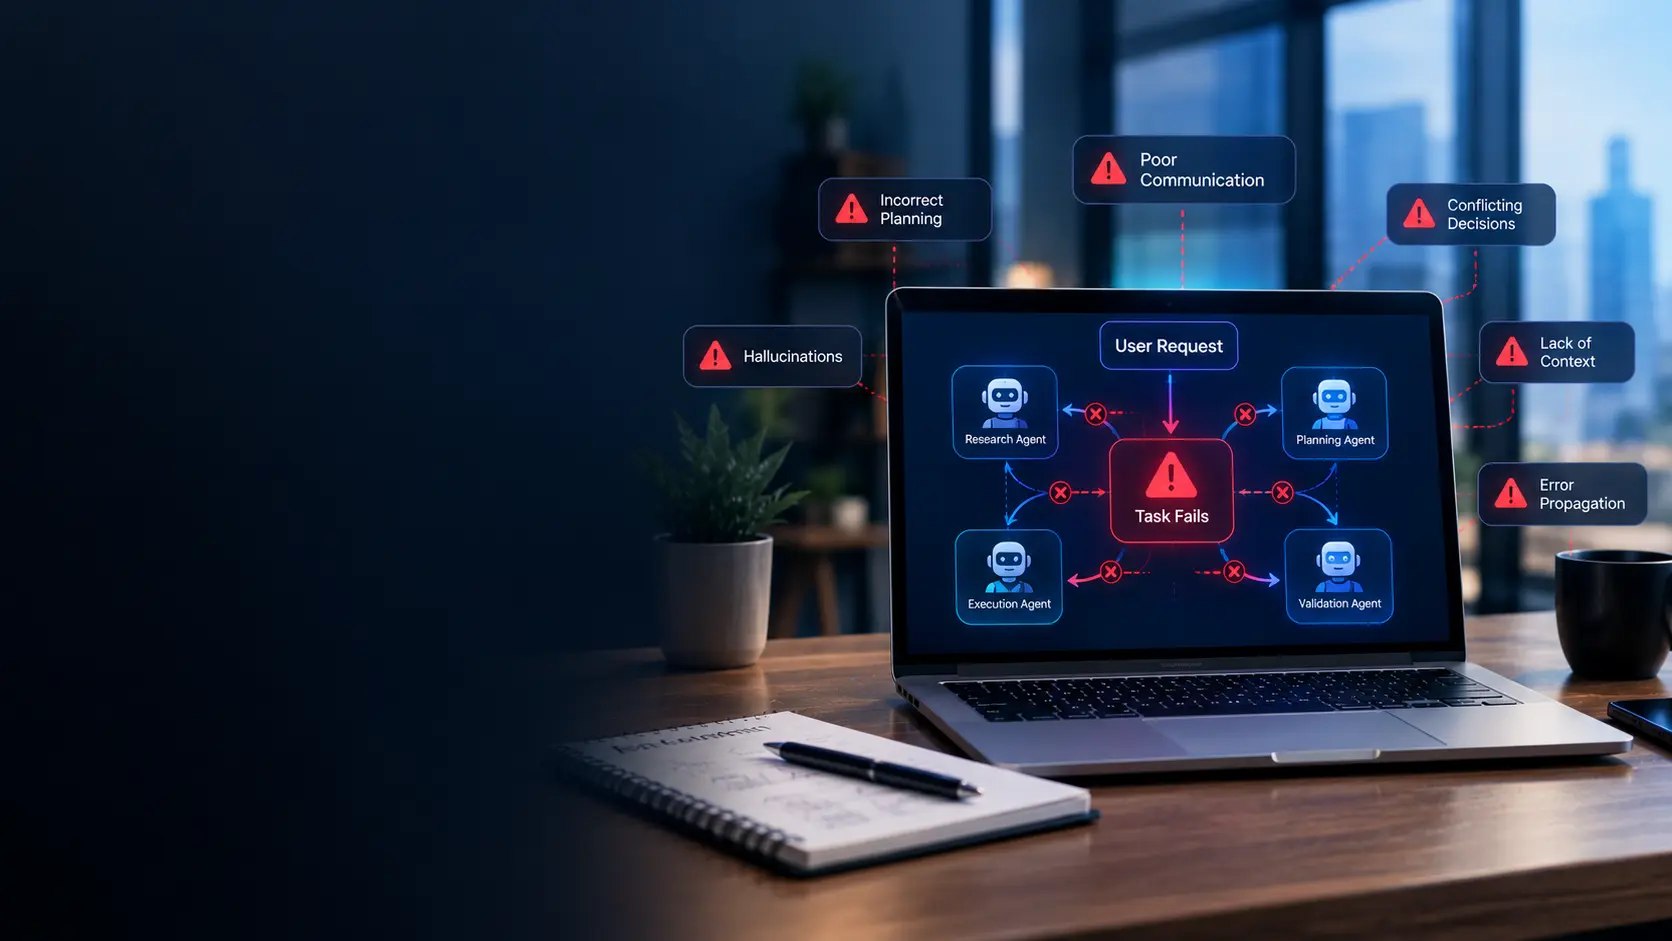
Key Takeaways According to statistics, multi-agent systems have a 41% to 86.7% failure rate. Some of the biggest reasons behind…